DeepSeek Open Sources DeepInfer Under Apache 2.0: Production Serving Engine for NVIDIA SM100 and Huawei Ascend 950
DeepSeek has open-sourced its production-grade offline inference runtime, DeepInfer, under the Apache 2.0 license. The system features FlashMLA, DeepGEMM FP8 kernels, and DSpark speculative decoding with native support for both NVIDIA SM100 and Huawei Ascend 950 silicon.
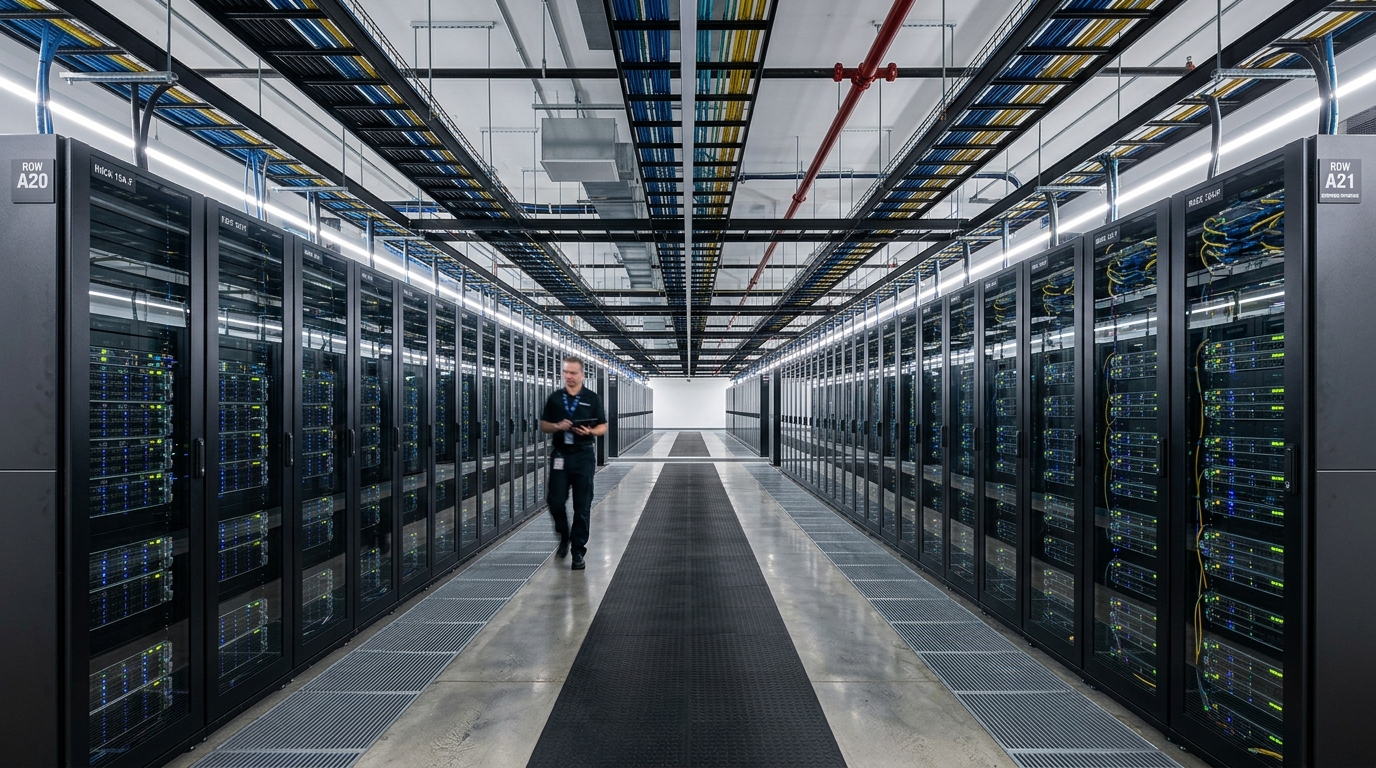
On the morning of October 21, 2026, Chinese frontier artificial intelligence laboratory DeepSeek published the open-source repository for DeepInfer under the Apache 2.0 license. DeepInfer represents the high-throughput, bare-metal offline inference engine deployed internally to power production API endpoints for the DeepSeek-V4.1-Flash model series.
The release represents a major milestone for distributed systems engineers, offering an unencumbered, micro-kernel optimized inference stack designed to maximize arithmetic intensity on next-generation accelerator hardware.
Custom Low-Level Kernels and Dual-Architecture Silicon Support
At the core of DeepInfer lies DeepSeek's proprietary suite of high-performance primitives: FlashMLA (an ultra-optimized Multi-Head Latent Attention operator), DeepGEMM (FP8 mixed-precision matrix multiplication routines), DeepEP (an all-to-all communication library engineered for Mixture-of-Experts routing), TileKernels, and DeepSelect. Crucially, the engine delivers co-equal, first-class compilation targets for both NVIDIA SM100 (Blackwell architecture) and Huawei's Ascend 950 NPU, bridging disparate silicon paradigms within a unified runtime codebase.
For large-scale multi-accelerator execution, DeepInfer orchestrates a three-tiered parallelism strategy combining Attention Data Parallelism, Context Parallelism for long-sequence context balancing, and Expert Parallelism driven by Expert Parallelism Load Balancing (EPLB) heuristics to eliminate straggler nodes. It also incorporates DSpark, a speculative decoding implementation leveraging an auxiliary confidence head to verify speculative draft tokens with minimal memory bandwidth consumption.
- Full Apache 2.0 open-source distribution of DeepSeek's internal model serving stack
- Native first-class support for NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs
- Embedded performance micro-kernels: FlashMLA, DeepGEMM FP8, DeepEP, and DeepSelect
- DSpark speculative decoding scheduling to compress autoregressive decode latency
- Companion release of deepseek-recipe, a deterministic Rust tokenizer and wire-protocol parser
Scope Boundaries and Ecosystem Integration
Alongside the core engine, DeepSeek released deepseek-recipe, a deterministic Rust library handling high-speed tokenization, JSON schema extraction, and streaming wire protocols. DeepSeek deliberately delineated the initial release boundaries: the runtime focuses strictly on node-level kernel execution, intentionally omitting distributed KV-cache cluster pooling and inter-replica ingress layers to allow clean integration into external container orchestrators like Kubernetes.
“By open-sourcing DeepInfer, we aim to provide the systems community with an uncompromising kernel execution core that eliminates runtime overhead and maximizes hardware arithmetic intensity on modern accelerator architectures.”
The release of DeepInfer equips infrastructure teams with a transparent, highly audited serving framework capable of driving production MoE models. By decoupling inference runtime performance from vendor-specific software stacks, DeepInfer accelerates the broader industry shift toward portable, open systems engineering.
References & Primary Sources
Related Analysis & Context
PHP2Shell Shakes Core PHP Runtime: Dual CVSS 9.2 Vulnerabilities Enable Unauthenticated RCE
The PHP core security team released emergency out-of-band updates addressing two critical memory management flaws (CVE-2026-109618 & CVE-2026-109619) dubbed PHP2Shell. The vulnerabilities exploit the C-level Zend Engine before application code executes, prompting urgent infrastructure patching across global web servers.
GCash Parent Mynt Debuts in Largest IPO in Philippine History: $7B Valuation and Record Retail Participation
Globe Fintech Innovations (Mynt), parent company of GCash, listed on the Philippine Stock Exchange raising up to ₱60.9 billion ($1.05B) in the country's biggest IPO ever, backed by disciplined pricing and 140,000 retail app investors.
Microsoft Unveils Guardian Agents: Securing the 'Agentic Insider' in the Enterprise
Microsoft has introduced Guardian Agents and expanded Project Perception in Microsoft 365 E7, treating autonomous AI agents as privileged 'agentic insiders' subject to continuous Dynamic Agent Risk scoring, tiered containment, and local shadow AI detection across 60 agent types.